Ethernet OAM Tools for Service Fault Isolation
Structured OAM tools help carriers pinpoint and fix Ethernet service faults faster than ever.
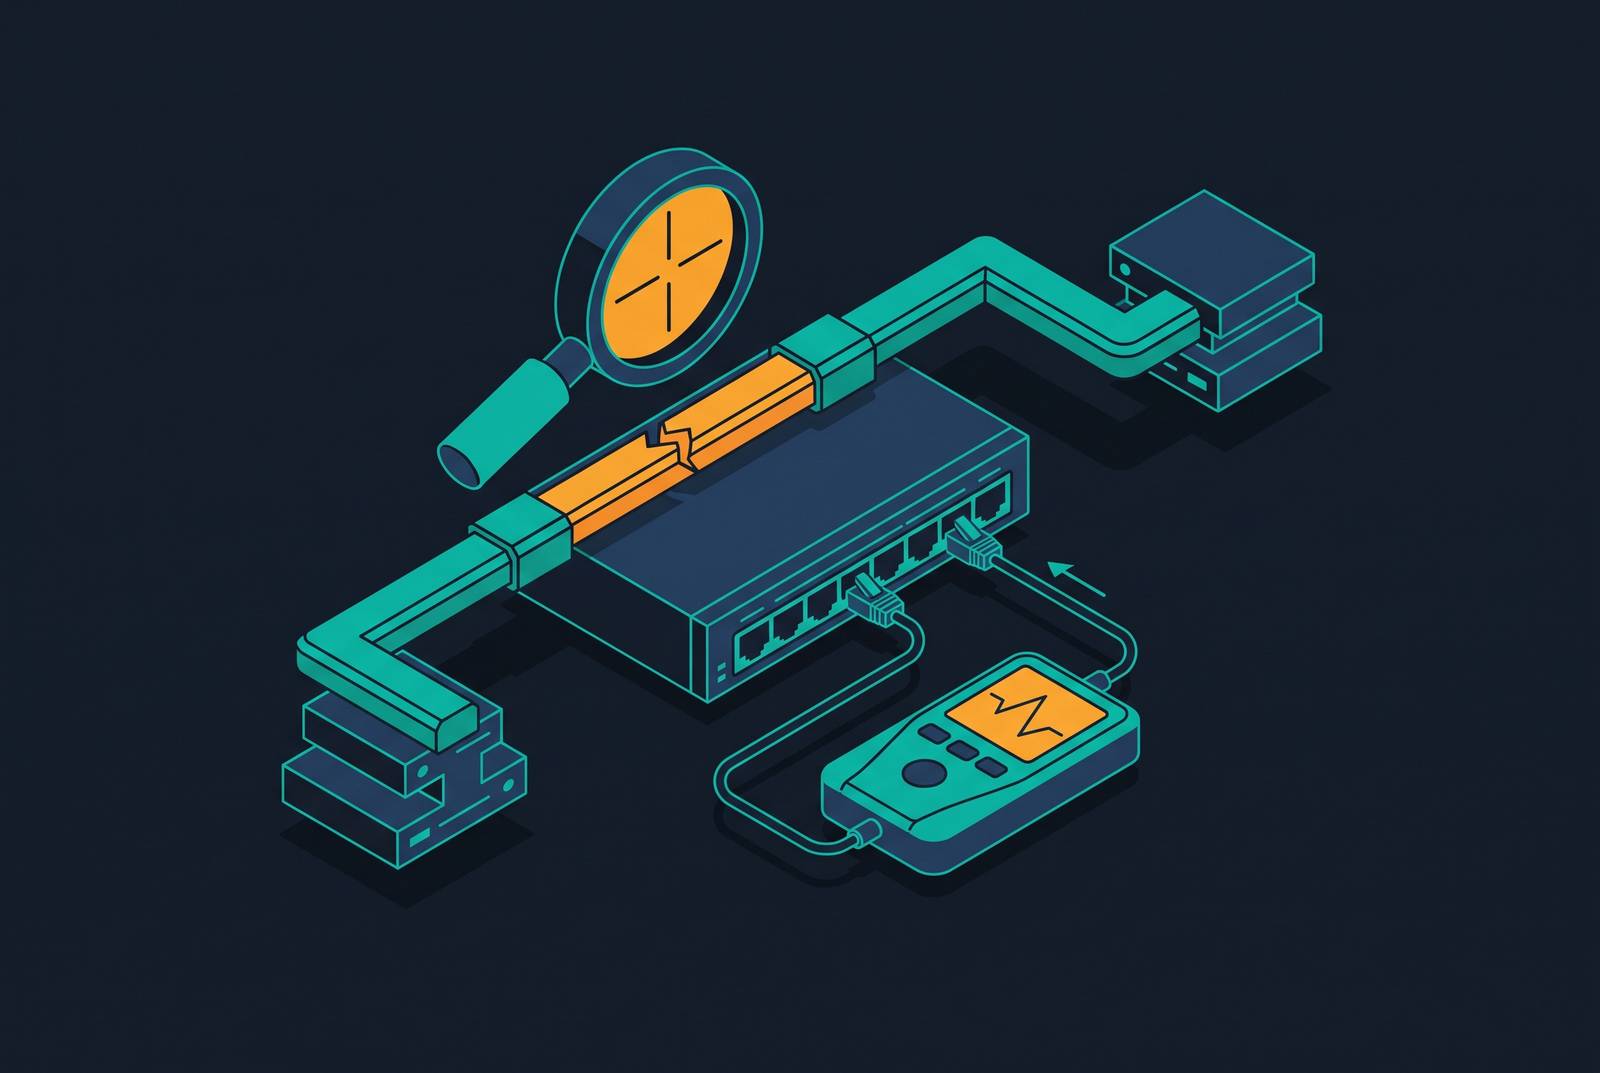
Ethernet OAM exists because Carrier Ethernet outgrew the network it was built on. It moved from enterprise LANs, where a dropped frame just meant a help desk ticket, into metro and wide-area networks spanning multiple operators, where a dropped frame means a broken service level agreement. That shift demanded a fault management toolkit Ethernet never had, and understanding that toolkit, layer by layer and domain by domain, is the practical foundation for isolating faults on any Carrier Ethernet service today.
Why Carrier Ethernet Networks Need Structured OAM
Ethernet was built for best-effort delivery on a shared local segment, not for the multi-operator, multi-hundred-mile services that now carry voice, video, and enterprise data under contractual performance guarantees. It had no native way to detect a fault, isolate where that fault sat, confirm it, or measure performance against a target. Carrier networks have always needed those four functions, and they needed them at scale, because the equipment came from different vendors and the contracts carried financial penalties.
EXFO's white paper frames this as the central challenge facing operators deploying Ethernet-based services: match the OAM support that existed in traditional carrier network technologies, because the service level agreement has to hold regardless of what moves the bits underneath it. If a customer buys an Ethernet Virtual Connection with a guaranteed level of availability, they don't care whether the transport is Ethernet, another networking technology, or something else. They care whether the circuit is up and how fast a fault gets fixed when it isn't.
Cisco's technical note on Connectivity Fault Management states the stakes directly: OAM translates directly to the competitiveness of the service provider. Speed and precision in fault isolation are not operational nice-to-haves; they determine which carriers survive in a market where enterprise customers can switch providers over a single missed SLA.
None of this works without structure. If you scatter diagnostic tools, each built for a different layer or a different vendor, you don't get carrier-grade fault management. The tools have to be organized into a hierarchy that mirrors how the network itself is organized, by domain, by operator, and by responsibility, so that isolating a fault in a multi-operator network doesn't require every operator to see into every other operator's infrastructure.
The Maintenance Domain Hierarchy and Fault Responsibility Across Operators
The maintenance domain model is what makes the rest of Ethernet OAM coherent. It divides a network into nested zones of responsibility, each with its own monitoring scope, so that a subscriber, a service provider, and an access provider can each run fault detection on their own piece of the network without stepping on each other's traffic or visibility.
Omnitron's explainer on end-to-end OAM lays out a real example using an E-Line service, a simple point-to-point Ethernet connection. Four domains, four maintenance associations, one service.
EXFO's white paper defines the building blocks that make this work. A maintenance domain is the portion of a network typically owned and operated by a single entity. MEPs, or maintenance entity group end points, sit at the edges of a domain, where they initiate and terminate OAM frames. Maintenance entity group intermediate points, or MIPs, sit inside a domain and don't initiate OAM traffic themselves, but they respond to loopback and link trace requests, which is what makes fault isolation at intermediate hops possible.
These domains are organized into eight levels, numbered 0 through 7, and the numbering isn't arbitrary. A higher-level domain's OAM frames pass straight through the equipment of a lower-level domain, so that equipment never intercepts or processes them. That's what enforces separation: a service provider monitoring an end-to-end EVC at a higher level doesn't disrupt the subscriber's own OAM running at a level below it, and an access provider running OAM on their own segment doesn't interfere with the service provider's broader view.
Within each domain, a maintenance association verifies the integrity of one specific service instance, tying together two or more MEPs, with MIPs along the way supporting detection and isolation at the points in between. Responsibility is assigned by architecture, not negotiated after the fact.
ITU-T Y.1731 and IEEE 802.1ag in the Fault Isolation Toolkit
Two standards govern this structure, and they do different jobs. IEEE 802.1ag defines Connectivity Fault Management, the framework of domains, MEPs, MIPs, and the fault-isolation mechanisms built on top of them. ITU-T Y.1731 extends that framework with performance monitoring, so you can verify SLA compliance on an Ethernet Virtual Connection basis and on a Class of Service basis. Neither standard replaces the other. Each covers a function the other doesn't.
Cisco describes CFM as an end-to-end, per-service-instance Ethernet layer OAM protocol, covering proactive connectivity monitoring, fault verification, and fault isolation across Ethernet networks far larger and more complex than a single enterprise LAN. EXFO's white paper separates the two functions cleanly: CFM, defined jointly across 802.1ag, Y.1731, and MEF 30.1, handles detecting, verifying, and isolating a connectivity failure. Performance monitoring, defined in Y.1731 and MEF 35, measures end-to-end service performance. Both run end-to-end, but they answer different questions: is the service broken, versus is the service meeting its performance targets.
The performance side matters just as much as the fault side for a provider holding an SLA. A connection can be technically up and still violate its contract if delay variation spikes during a video call or frame loss creeps past the threshold a customer pays to avoid.
802.1ag, meanwhile, handles both point-to-point and multipoint connections and uses multicast packets alongside unicast, and that matters because you need VLAN-level operations across infrastructure shared by multiple customers. If a provider runs thousands of VLANs across one physical network, it needs a fault management protocol that can scale its monitoring across all of them without a dedicated unicast session for every pair of endpoints. The MEF has added further service OAM requirements on top of both standards in MEF 17, rounding out a layered set of specifications. Treating 802.1ag and Y.1731 as alternatives misses the point. They're two layers of the same capability, one built to find and isolate faults, the other built to prove the service is performing as promised.
How Continuity Check, Link Trace, and Loopback each play a distinct role in isolating a fault
CFM puts three tools into an operator's hands, and you run them in sequence. Continuity Check detects that something is wrong. Link Trace finds where along the path the problem sits. Loopback confirms the fault at that specific point. Running these out of order, or treating them as interchangeable, wastes time during an incident and risks a wrong diagnosis.
Continuity Check messages, or CCMs, start the sequence. Omnitron describes CCM as a periodical keep-alive message exchanged between the endpoints of an Ethernet service within a domain level, providing proactive fault monitoring with automatic notification. EXFO compares it to a heartbeat, and the interval between heartbeats can be tuned to one of seven standard settings, including 3.3 milliseconds, 10 milliseconds, 100 milliseconds, and 1 second, down to 10 seconds. CCMs maintain adjacency at the VLAN level, and when a remote MEP stops sending its heartbeat, the local MEP raises a defect condition and fires a fault notification. That's the full extent of what Continuity Check does. It tells you something broke. It doesn't tell you where.
Link Trace picks up from there. The mechanism that makes this work is the MIP. Intermediate points along the path respond to Link Trace messages even though they don't generate OAM traffic on their own, so an operator can trace a fault hop by hop without a full MEP at every point in the network.
Loopback closes the sequence. Loopback's job is to confirm it precisely, not to search for it. Running these three tools in order, detection, then location, then confirmation, turns a CCM alarm into an actionable fault report.
Where IEEE 802.3ah link-layer OAM fits when the fault is below the service layer
CFM operates at the service layer, and it has a blind spot by design: it can't see physical problems on an individual link between two directly connected devices. That's the gap IEEE 802.3ah fills. Where CFM runs end-to-end across a maintenance domain, 802.3ah runs between adjacent peers on a single segment, one device talking to the device immediately next to it.
The standard gives an operator three core capabilities: link discovery, which identifies the neighboring device on a single link; fault detection at the physical layer; and remote loopback. 802.3ah runs on full-duplex point-to-point links, and it's what lets a technician diagnose an individual connection before the service layer above it is even reachable.
The division of labor between the two standards follows the order a fault actually unfolds. A CCM defect surfaces in CFM, Link Trace narrows the fault to a specific access segment, and then 802.3ah confirms whether the trouble is a physical link failure or a misconfiguration at the service layer. CFM and 802.3ah are not competitors. They answer different questions at different layers, and a complete fault isolation process needs both.
When CFM hands off to technology-specific OAM for faults inside virtual circuits
CFM's reach stops at the Ethernet layer. When the isolated fault path runs through an MPLS pseudowire or another virtual circuit technology, CFM cannot diagnose further on its own, because the data plane inside that circuit isn't Ethernet anymore. Cisco's technical note is direct about the handoff: once a fault points to a virtual circuit, the operator moves to OAM tools built for that specific technology, such as VCCV and MPLS ping for MPLS pseudowires.
That handoff isn't a flaw in the standards. A loopback message built for Ethernet doesn't mean anything inside an MPLS label-switched path, so a separate, purpose-built tool has to take over.
The consequence for operators is structural. Fault isolation across a network that mixes Ethernet, MPLS, and other technologies is a sequential process that moves across multiple tools, not something a single diagnostic interface can complete under today's standards. A CLEC running fiber-to-the-home, dedicated internet access, and Carrier Ethernet at the same time ends up managing at least three separate OAM stacks, and each one comes with its own alarms, its own correlation logic, and its own ticketing integration. OAM standards are written with one protocol family per data plane, and operators have to plan their operations support systems around that reality.
OAM Telemetry and the Unified Operational Record
An OAM fault signal is generated at the protocol layer, but the response to it, the ticket, the technician dispatch, the customer notification, happens at the OSS layer. When those two layers sit in disconnected systems, the time between detection and resolution stretches, and that stretch counts directly against the SLA clock.
When OAM telemetry crosses out of a CFM domain into a ticketing or provisioning system built on a different network model, correlating the fault to the right service record becomes a manual step. That manual correlation happens at exactly the moment the SLA clock is running fastest, when every minute between detection and dispatch is a minute counted against the provider's contractual commitment. The same principle that makes a qualification error expensive if it surfaces at provisioning, rather than earlier, applies to OAM faults: catching a misidentified segment at the CFM layer, before a truck rolls, costs little. Catching it after the truck rolls costs a great deal more.
Omnitron's four-domain picture of a single E-Line service, subscriber, service provider, access provider, and the access provider's own segment, shows how this can go wrong. Four domains map naturally to four different records if each stakeholder runs a separate OSS with its own network model. When a fault hits, each system has its own version of who owns the circuit, and a dispute over responsibility becomes close to guaranteed, because the data the hierarchy produced never reached a single operational record capable of acting on all of it at once.
What governed, AI-native OSS makes possible when it operates on the same data as OAM
The fix is structural, matching the structure of the problem. An AI-native OSS that runs on the same APIs, audit trails, and permission structures used by human operators can take OAM fault telemetry from the moment of detection through a correlated ticket to a remediation action, inside one governed workflow, without the delay that cross-system reconciliation adds.
The distinction from AI bolted onto legacy tools matters here. Instead of a machine learning model sitting on top of a separate alarm console, AI agents operating inside a unified system act on the same service record that qualification, design, provisioning, and activation were already built on. A CFM defect condition maps automatically to the correct circuit, the correct customer, and the correct SLA, because there's only one record for all of those functions to begin with.
Governance is what keeps this safe to run. When an agent triggers a configuration check, routes an exception, or updates an incident record, that action lands in the same audit trail as the human operator who originally designed the service, bound by the same permission limits. Shadow automation, action taken outside that audit trail, is excluded by the architecture itself, not by policy alone.
This lines up directly with how the maintenance domain hierarchy already assigns responsibility. If CFM isolates a fault to the access provider's maintenance domain, a governed system can route the resulting action to that party without a human dispatcher sitting in the middle, translating one system's language into another's. For a CLEC or fiber operator juggling fiber-to-the-home and Carrier Ethernet at once, this is what turns the multi-stack reality described earlier into something manageable: a single data model that takes in telemetry from 802.3ah, CFM, and MPLS OAM alike, and treats every one of them as an event against a service record, rather than as a separate alarm demanding a separate team to interpret it.